1. Introduction
Unsupervised Learning is an important concept in machine learning and Artificial Intelligence.
Unsupervised learning works with unlabeled data while Supervised learning works with trained models using labeled data.
In unsupervised learning, the algorithm tries to discover hidden patterns, structures, or relationships within the dataset without being given the correct answers.
Where we use Unsupervised learning?
Ans: Unsupervised learning is widely used in areas such as customer segmentation, recommendation systems, fraud detection, and market analysis.
2. Syntax
You can implement Unsupervised learning algorithms using Python and machine learning libraries such as Scikit-learn.
Below is a simple example using the K-Means clustering algorithm.
from sklearn.cluster import KMeans

# Dataset
data = [[1,2], [1,4], [1,0],
       [10,2], [10,4], [10,0]]

# Create model
model = KMeans(n_clusters=2)

# Train model
model.fit(data)

# Predict clusters
print(model.labels_)
This code groups the dataset into clusters based on similarities.
Step-by-Step Understanding
Dataset:
[1,2], [1,4], [1,0]
[10,2], [10,4], [10,0]
You can clearly see two natural groups:
Cluster 1 (around x = 1):
[1,2]
[1,4]
[1,0]
Cluster 2 (around x = 10):
[10,2]
[10,4]
[10,0]
When KMeans(n_clusters=2) runs, it will group the first three points together and the last three points together.
Output
or it may also appear as:
[1 1 1 0 0 0]
Why Two Possible Outputs?
In K-Means, the cluster numbering is arbitrary.
So cluster 0 and 1 can swap, but the grouping will remain the same.
Final Meaning
| Data Point | Cluster |
|---|---|
| [1,2] | 0 |
| [1,4] | 0 |
| [1,0] | 0 |
| [10,2] | 1 |
| [10,4] | 1 |
| [10,0] | 1 |
✔ First three points → Cluster A
✔ Last three points → Cluster B
3. Example
Let’s look at a simple example where an algorithm groups customers based on their purchase behavior.
Python Example
from sklearn.cluster import KMeans

# Customer data
customers = [
   [20, 2000],
   [25, 2200],
   [45, 5000],
   [50, 5200],
]

# Create model
model = KMeans(n_clusters=2)

# Train model
model.fit(customers)

# Cluster labels
print("Customer Groups:", model.labels_)
In this example, the algorithm groups customers into clusters based on similarities in the dataset.
This program uses K-Means Clustering from scikit-learn to divide customers into 2 clusters based on Age and Income.
Dataset
[20, 2000]
[25, 2200]
[45, 5000]
[50, 5200]
You can see two clear groups:
Group 1 (younger customers with lower income):
[20, 2000]
[25, 2200]
Group 2 (older customers with higher income):
[45, 5000]
[50, 5200]
Expected Output
or it could also be
Customer Groups: [1 1 0 0]
Why Two Possible Outputs?
In K-Means, the cluster numbers (0 and 1) are assigned automatically, so they can swap.
But the grouping of customers remains the same.
Interpretation
| Customer | Age | Income | Cluster |
| 1 | 20 | 2000 | 0 |
| 2 | 25 | 2200 | 0 |
| 3 | 45 | 5000 | 1 |
| 4 | 50 | 5200 | 1 |
✔ Cluster 1: Young, low-income customers
✔ Cluster 2: Older, high-income customers
Cluster Centers (Approx.)
After training, the centroids will be approximately:
Cluster 1 center ≈ [22.5, 2100]
Cluster 2 center ≈ [47.5, 5100]
4. Real-world Example
Unsupervised learning is used in many real-world AI applications.
1. Customer Segmentation
Companies analyze customer data to group users based on behavior and preferences.
Online marketplaces such as Amazon use this technique to understand shopping patterns.
2. Recommendation Systems
Streaming platforms like Netflix group users with similar viewing habits and recommend content accordingly.
3. Fraud Detection
Financial institutions use unsupervised learning to detect unusual patterns in transactions, which helps identify fraudulent activities.
4. Image and Pattern Recognition
Unsupervised learning algorithms are used to analyze images and detect patterns without labeled data.
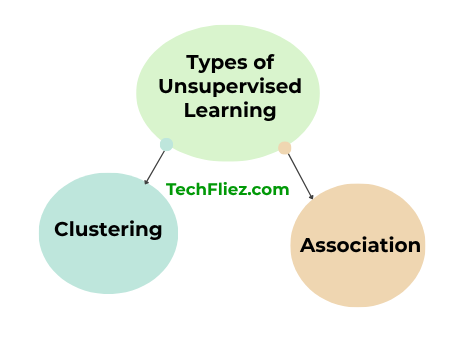
5. Types of Unsupervised Learning
Unsupervised learning mainly includes two types.
1. Clustering
Clustering algorithms group similar data points together.
Examples include:
- K-Means Clustering
- Hierarchical Clustering
- DBSCAN
Clustering is commonly used in customer segmentation and recommendation systems.
2. Association
Association algorithms identify relationships between variables in large datasets.
A common example is market basket analysis, which helps retailers understand which products are frequently purchased together.
6. Advantages of Unsupervised Learning
Unsupervised learning offers several benefits:
- Works with unlabeled data
- Helps discover hidden patterns in large datasets
- Useful for exploratory data analysis
- Widely used in recommendation systems and clustering tasks
7. Limitations of Unsupervised Learning
Despite its advantages, unsupervised learning has some limitations.
- Results can be difficult to interpret
- Accuracy may vary depending on dataset quality
- Choosing the right number of clusters can be challenging
8. Conclusion
Unsupervised learning is used to discover hidden patterns in unlabeled data. It plays a key role in applications such as recommendation systems, customer segmentation, fraud detection, and market analysis.
Note: Unsupervised learning is a powerful machine learning technique.
Unsupervised learning does not require labeled datasets, making it useful when large amounts of unlabeled data are available.